Your first graph
You’ll build the smallest graph that does something useful: paste messy notes, get back a to-do list. It takes a chat box, a model, and a view of the conversation. Then you’ll give the model standing instructions with a Template, so you only have to paste the notes.
1. Start a new graph
Section titled “1. Start a new graph”In the Workflows list on the left, press New workflow. A new tab named untitled opens with an empty canvas.
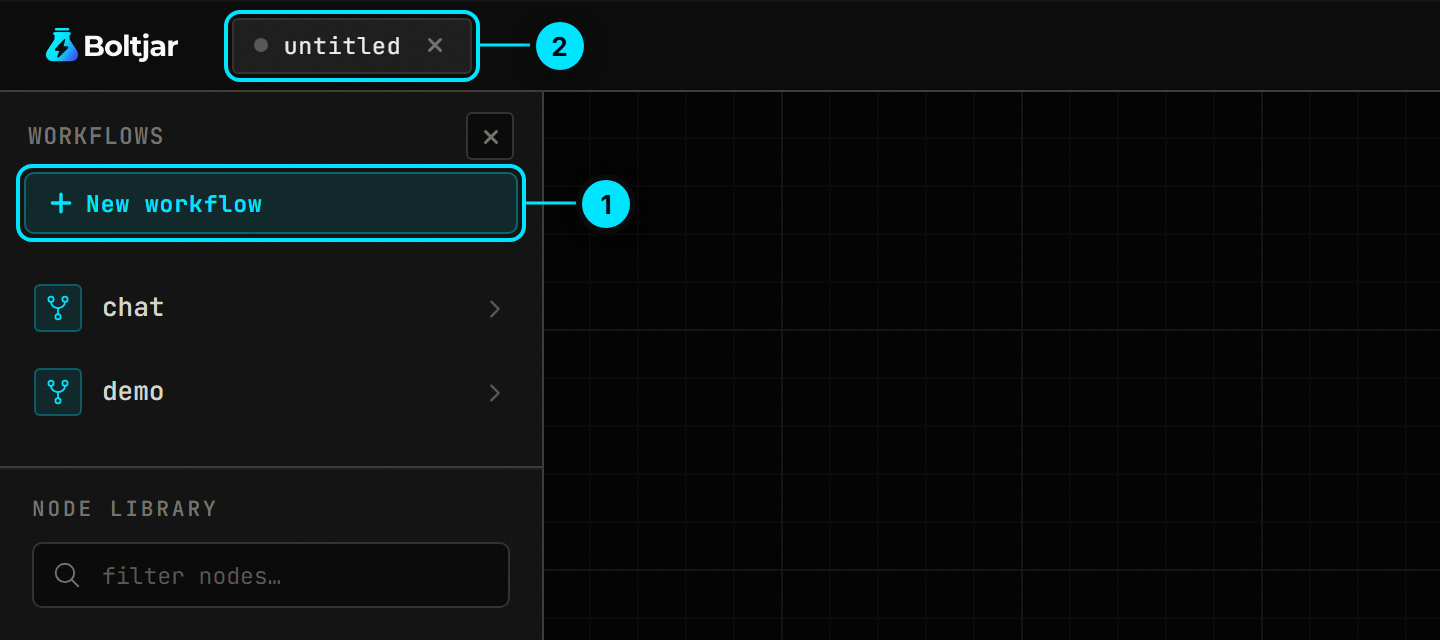
- New workflow, at the top of the Workflows list.
- The new tab,
untitled, with an empty canvas below it.
2. Add three nodes
Section titled “2. Add three nodes”From the node library on the left, add a Chat Input, an LLM and a Chat node: click a node to drop it on the canvas, or drag it where you want it. You can also double-click an empty spot of the canvas and search.
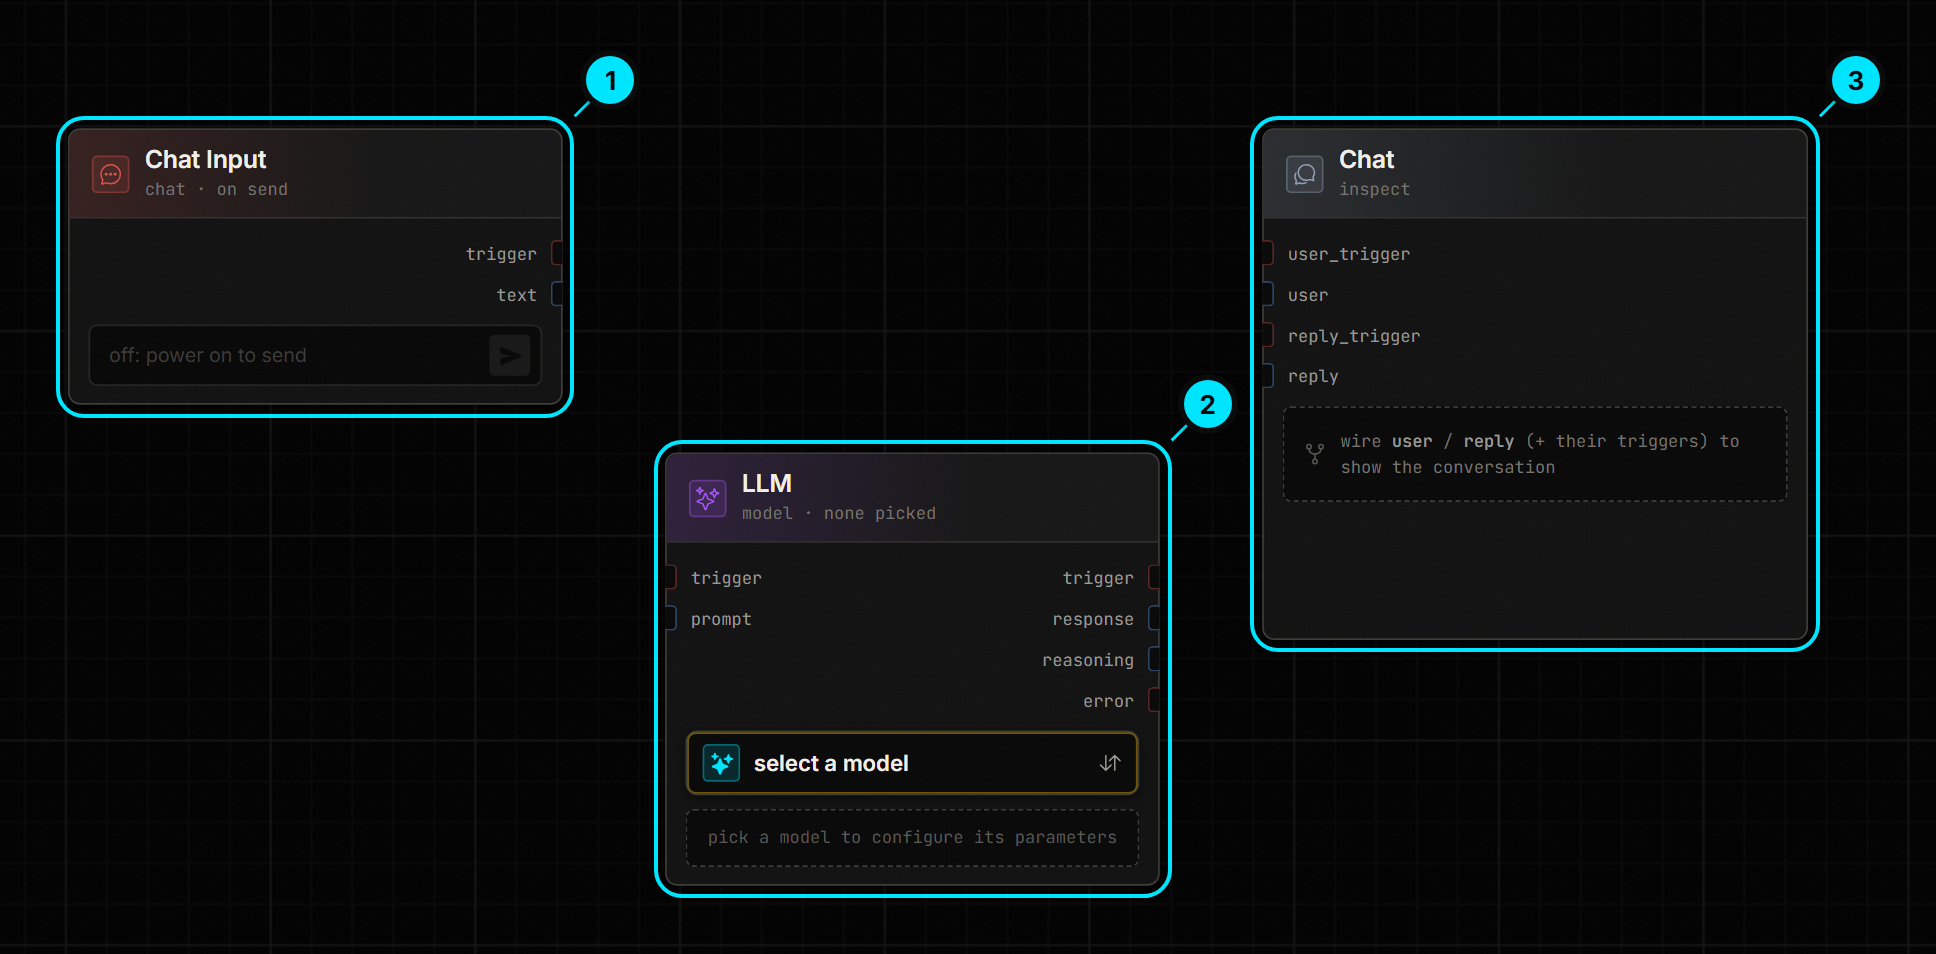
- Chat Input: the box you type into. Its outputs are
triggerandtext. - LLM: the model. It says select a model until you pick one.
- Chat: the conversation, your messages and the replies.
3. Wire them
Section titled “3. Wire them”Drag from an output (the dots on the right of a node) to an input (the dots on the left):
| From | To | What it carries |
|---|---|---|
Chat Input trigger |
LLM trigger |
the signal to run |
Chat Input text |
LLM prompt |
your message |
Chat Input trigger |
Chat user_trigger |
the signal to add your turn |
Chat Input text |
Chat user |
your message, for the view |
LLM trigger |
Chat reply_trigger |
the signal that the reply is ready |
LLM response |
Chat reply |
the reply |
A wire only lands where the types fit. The red ports carry events, the blue ones text; Typed pipes has the full list.
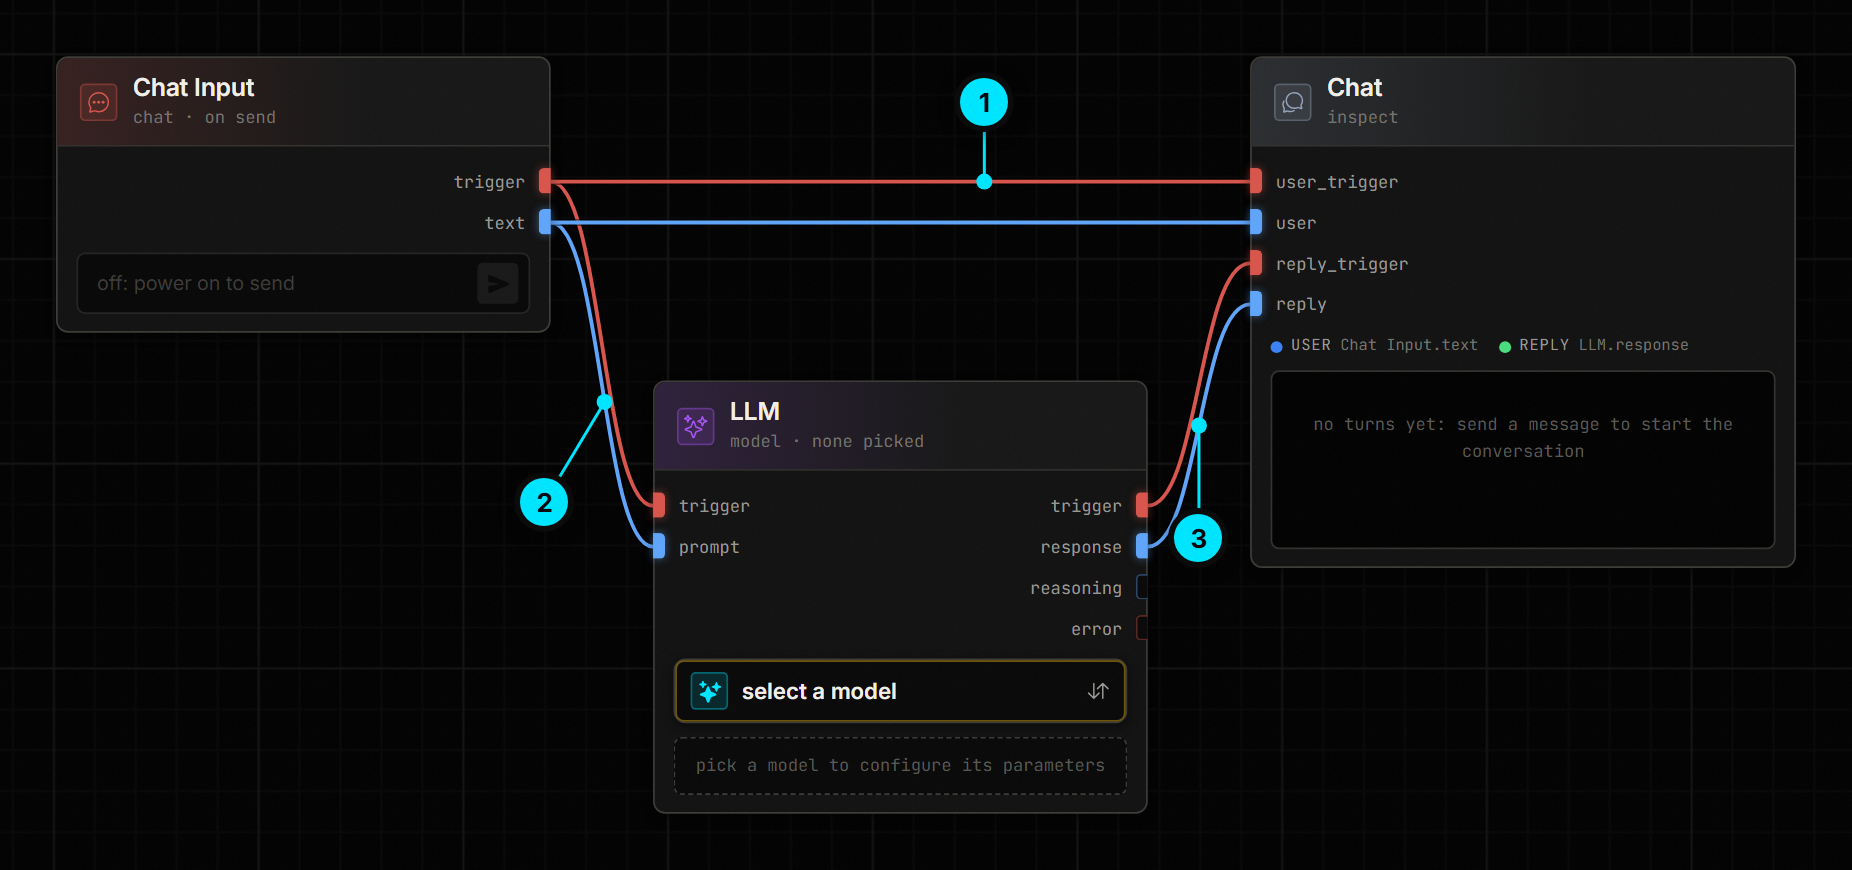
- A red wire carries an event: here Chat Input
triggerinto Chatuser_trigger. - A blue wire carries text: Chat Input
textinto the LLM’sprompt. - The reply: LLM
responseinto Chatreply, next to thetriggerthat says it is ready.
The Chat Input sends both of its outputs to two nodes, so two of its wires cross next to it. A crossing changes nothing: each wire still joins the two ports it joins.
4. Pick a model
Section titled “4. Pick a model”Open the model picker on the LLM node and choose a model. The picker lists the models your connected providers offer; for a local one, install Ollama and pull a model first (Install shows how). This page uses Gemma 4 12b on Ollama (ollama pull gemma4:12b).
You can also leave it empty: with no model picked, the LLM node answers with a mock reply, which is enough to see the graph work before any model is set up.
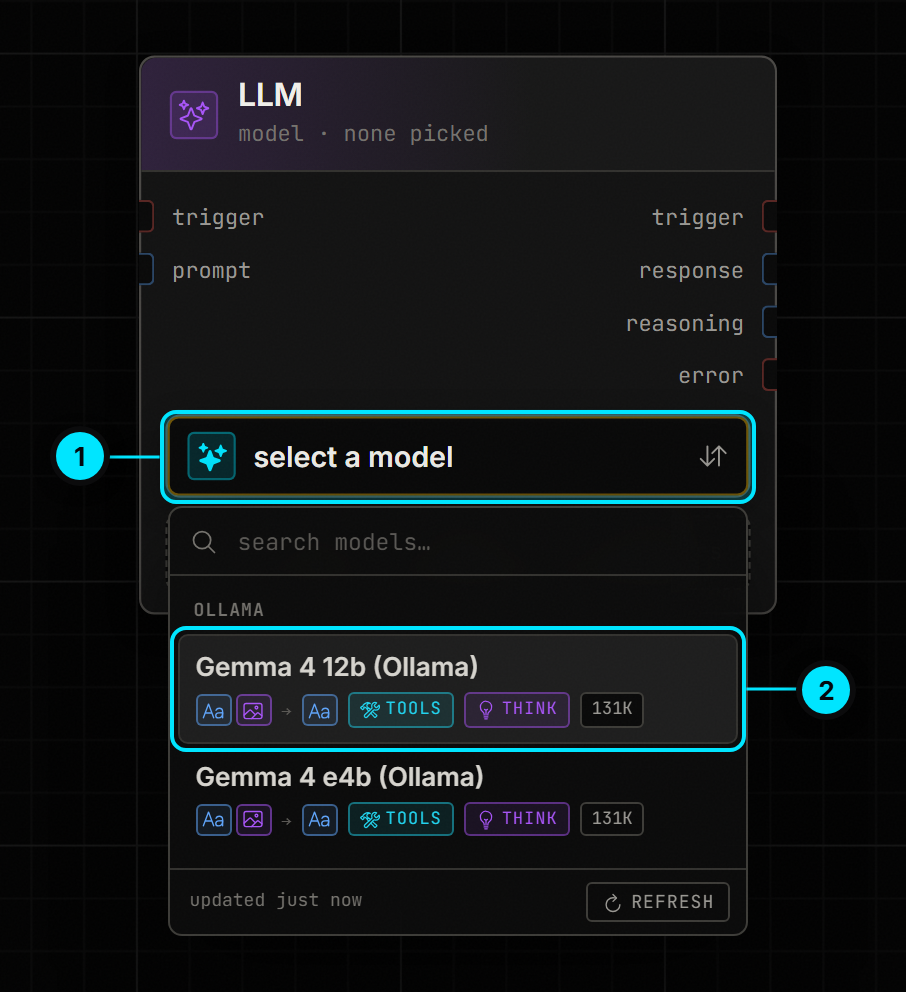
- The picker says select a model until you pick one. Boltjar never picks one for you.
- Gemma 4 12b (Ollama), the model this page picks. The list shows the chat models your providers offer; with none connected yet, it offers Add a connection instead, which opens Settings on AI Providers.
5. Turn it On
Section titled “5. Turn it On”Press On at the top. The server checks the graph first; if something is missing, the graph stays Off and the problems list says what. Once it is On, type into the Chat Input’s box and send:
to-do list, one line each: call the plumber about the leak, renew passport before June, buy Ada a birthday giftThe wires light up as values pass, and the reply lands in the Chat node.
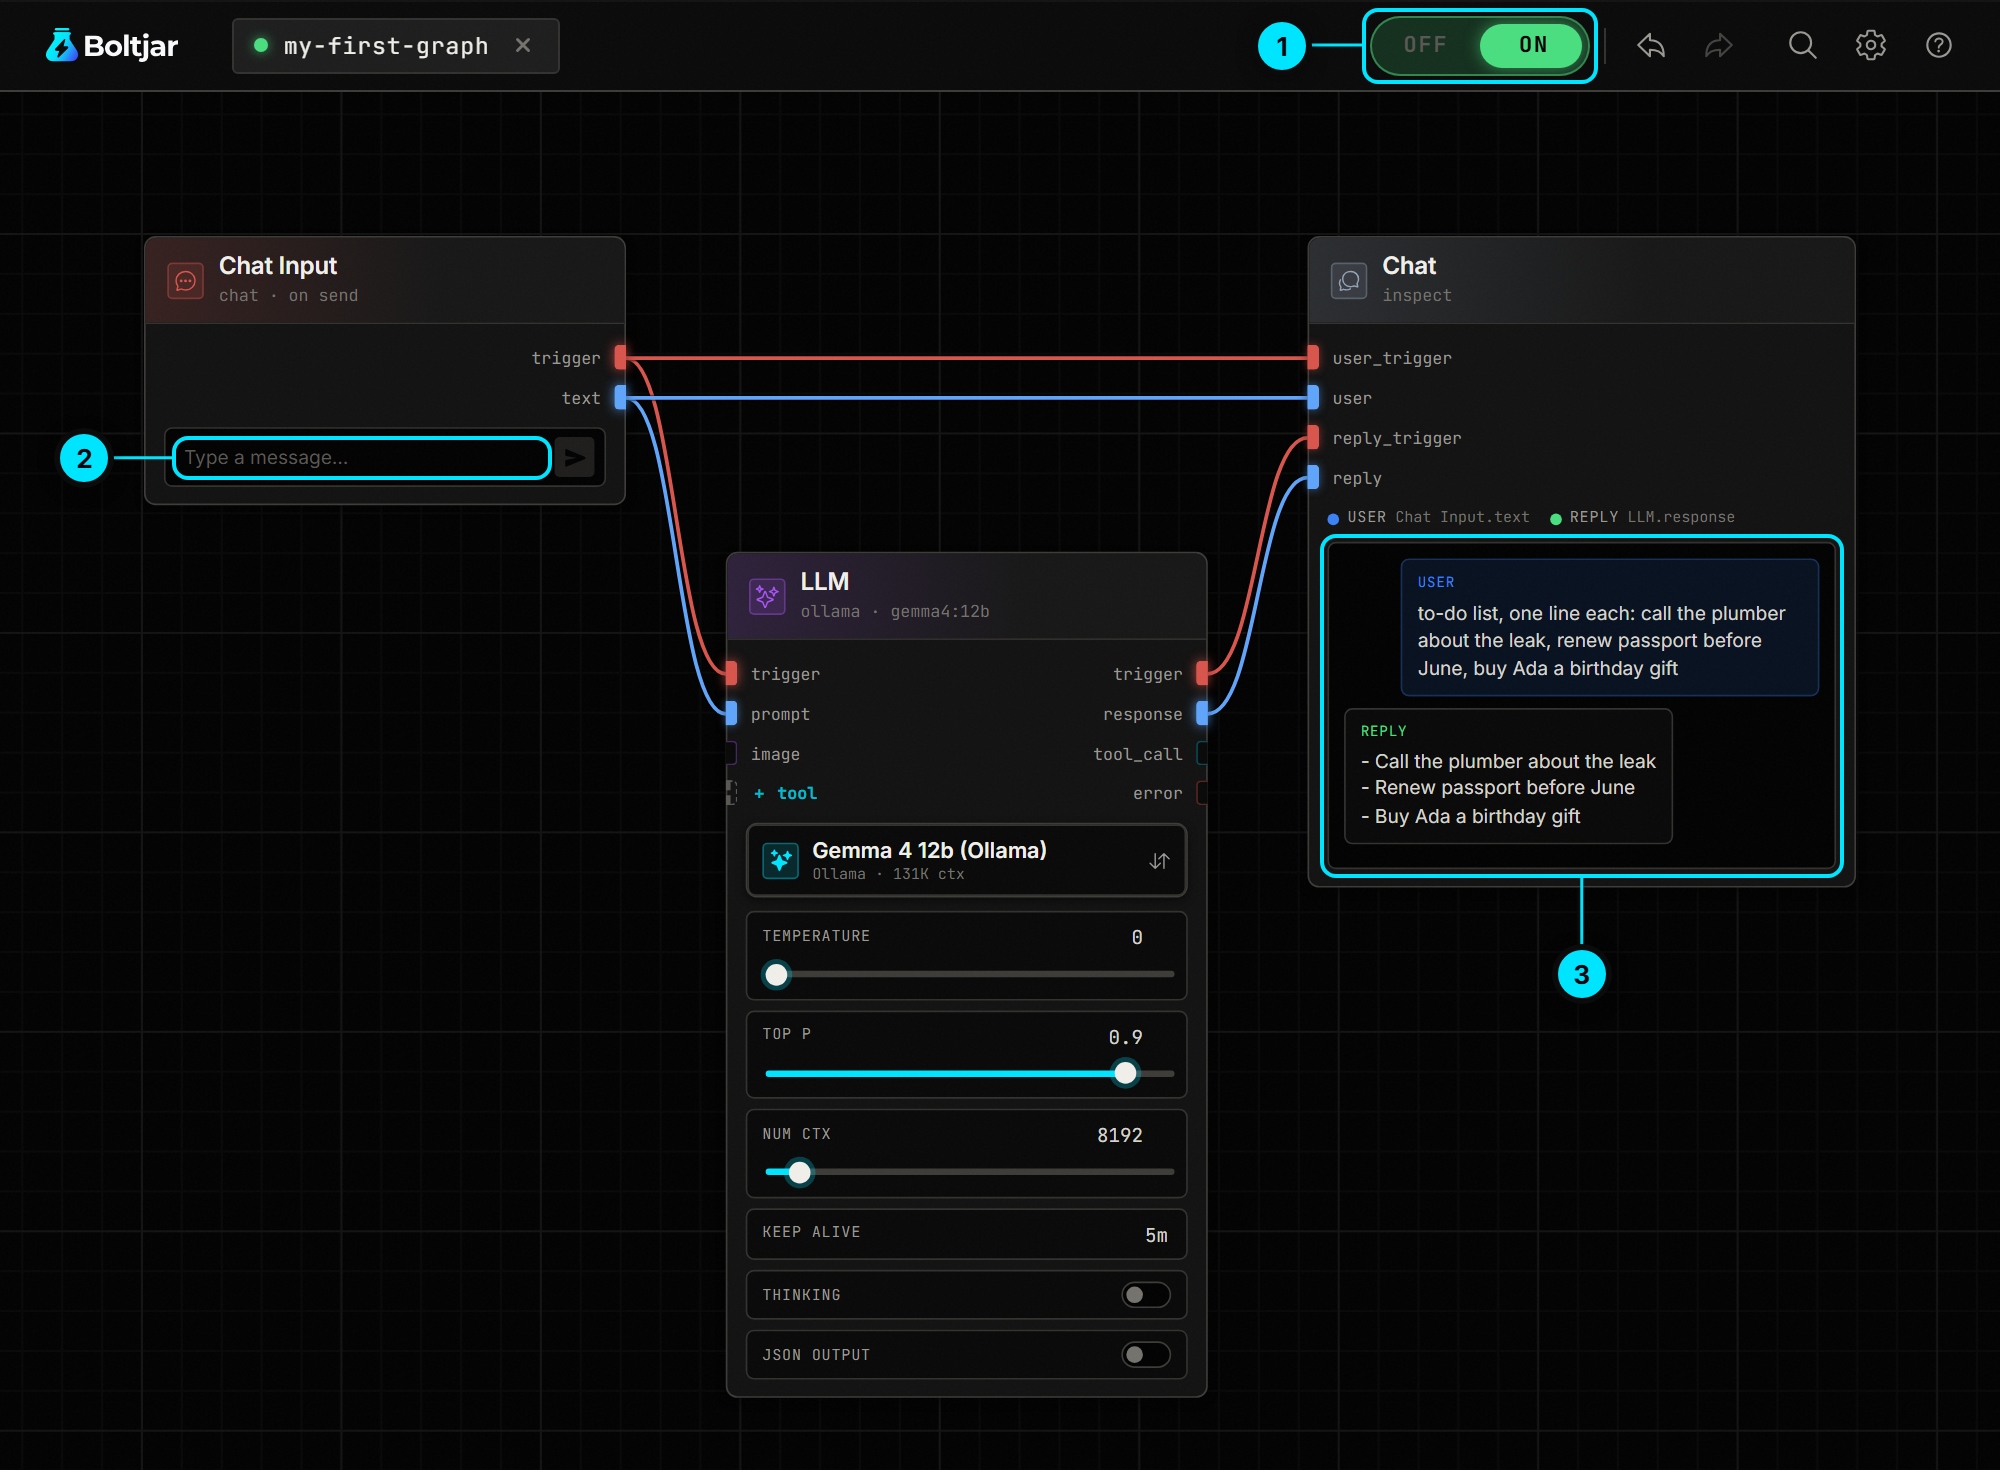
- The power switch, now on On.
- Type here and press Enter.
- Your message and the reply, here after you pick Gemma 4 12b. With no model picked, the reply is the mock instead:
[mock]and then the prompt it got, here your message.
6. Give the model instructions
Section titled “6. Give the model instructions”Typing “to-do list, one line each” before every note gets old. Put the instruction in a Template instead, and the Chat Input only needs the notes. Add a Template node and type into it:
You turn messy notes into a short to-do list, one task per line, most urgent first.
Notes: {message}
The {message} tag becomes an input socket. Wire it up:
| From | To |
|---|---|
Chat Input trigger |
Template trigger |
Chat Input text |
Template message |
Template trigger |
LLM trigger |
Template out |
LLM prompt |
The last two replace the LLM’s old wires, since an input holds one wire. Every trigger input needs a wire, the Template’s included, or the graph stays Off. The graph is now a draft of what is running, so press Save & Restart to run the new version.
Now send just the notes, call the plumber about the leak, renew passport before June, buy Ada a birthday gift, and the list comes back with the most urgent task first. With no model picked, the mock still answers [mock] and the start of the prompt it got, which now begins with the Template’s instruction.
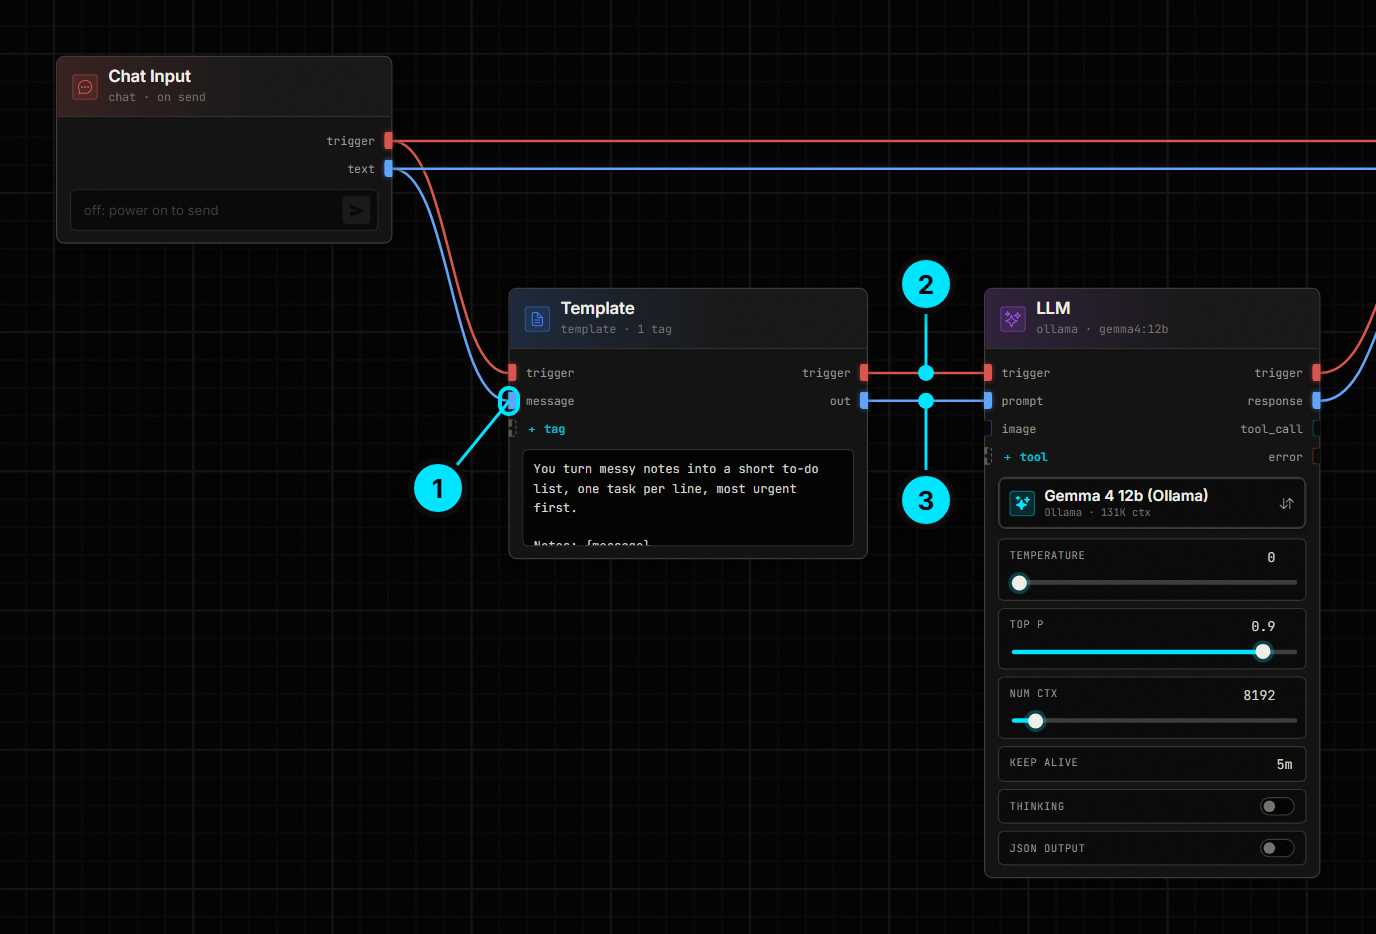
- The
messagesocket that the{message}tag made, wired to Chat Inputtext. - The trigger now runs through the Template: Template
triggerinto LLMtrigger. - The finished text: Template
outinto LLMprompt.
What just happened
Section titled “What just happened”Sending a message fired the Chat Input’s trigger. The Template ran on it, assembled its text from the message it read from the Chat Input, and passed the trigger on. The LLM runs when a trigger reaches it, and at that moment it pulled its prompt: the text the Template had just assembled. When the model answered, the LLM set response and fired its own trigger, and the Chat node added the reply.
That is the whole model of Boltjar: triggers push, data is pulled. Triggers and pulled data goes through it in detail.
Where it is saved
Section titled “Where it is saved”Save writes the graph to user/graphs/<name>.json and keeps a timestamped copy in user/autosave/<name>/ (the newest 50), so you can go back. Between saves, the editor keeps your edits in the browser, so a refresh loses nothing.
The finished graph from this page, with the Template, is the Chat with Ollama guide’s download, where the Chat Input is named Message and the Template Prompt.
When the browser holds another copy
Section titled “When the browser holds another copy”Your edits between saves are a draft in this browser. When a graph was saved somewhere else since that draft began (another browser, the MCP server, or another tool writing the same file), opening it shows the saved file, and your unsaved changes are kept aside, never dropped. A toast at the bottom right says so, with two buttons:
- Show my unsaved changes (15 nodes) puts your changes on the canvas and the saved file aside in their place. The buttons then read Back to the saved file (16 nodes) and Keep my changes (unsaved), so every choice can be taken back with one click.
- Delete my unsaved changes drops them. The saved file is unchanged.
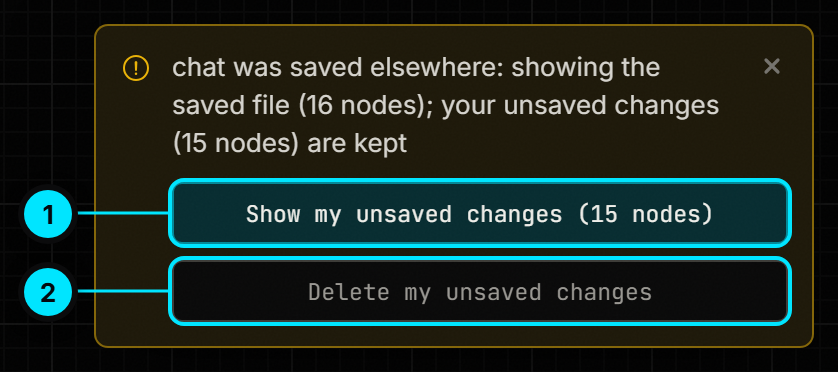
- Show my unsaved changes, with the number of nodes in them.
- Delete my unsaved changes.
The toast stays until you press one of its buttons or its ×. The × only hides it: the console line keeps the same two buttons, and the command palette (Ctrl+K, or Cmd+K on macOS) has the same choices. A choice made in any of the three settles all of them.
A draft left by an older version of Boltjar cannot tell whether it held edits, so it is called an older copy instead: Show the older copy and Delete the older copy. Both copies are always named with their node counts, so you can tell them apart.
The command palette also has Revert to the saved file: it puts the saved file back on the canvas, and any unsaved changes are kept aside and offered back in the same way.