Chat with Ollama
Paste a blunt work message and get it back clear and kind, ready to send. A chat box, a prompt with your instructions, a local model and a view of the conversation. Everything runs on your machine, so you can paste a message about a customer or a colleague without sending it to anyone.
Download the graph and save it in user/graphs/ inside your Boltjar folder; it shows up in your saved graphs. Or build it yourself below. The graph is MIT-0: copy it and license what you build from it however you like.
1. Pull a model
Section titled “1. Pull a model”ollama pull gemma4:12bThe figures on this page use Gemma 4 12b, about 8 GB on disk. Any Ollama chat model you pull shows up in the LLM’s picker; the LLM node’s page lists the ones that ship with a manifest.
The downloaded graph has no model picked, because a model can cost money and Boltjar never picks one for you. Until you pick one, the LLM answers with a mock reply.
2. The nodes
Section titled “2. The nodes”| Node | Settings |
|---|---|
| Chat Input, named Message | placeholder Paste a message to rewrite... |
| Template, named Prompt | the text below |
| LLM | model: pick Gemma 4 12b (Ollama), or the model you pulled |
| Chat | none |
The Prompt’s text:
You rewrite short work messages so they read clear and kind. Reply with the rewrite only.
Message: {message}
“Reply with the rewrite only” keeps the model from adding a greeting or an explanation, so the reply is ready to copy.
3. The wires
Section titled “3. The wires”| From | To |
|---|---|
Message trigger |
Prompt trigger |
Message text |
Prompt message |
Prompt trigger |
LLM trigger |
Prompt out |
LLM prompt |
Message trigger |
Chat user_trigger |
Message text |
Chat user |
LLM trigger |
Chat reply_trigger |
LLM response |
Chat reply |
A wire dropped on the Prompt’s + tag socket makes a tag named after the node it comes from, so Message text becomes {message}. Every trigger input needs a wire, the Prompt’s included, or the graph stays Off. The trigger runs through the Prompt to the LLM: the message fires the Prompt, which fills in its text once and fires the LLM, so one message runs the model once.
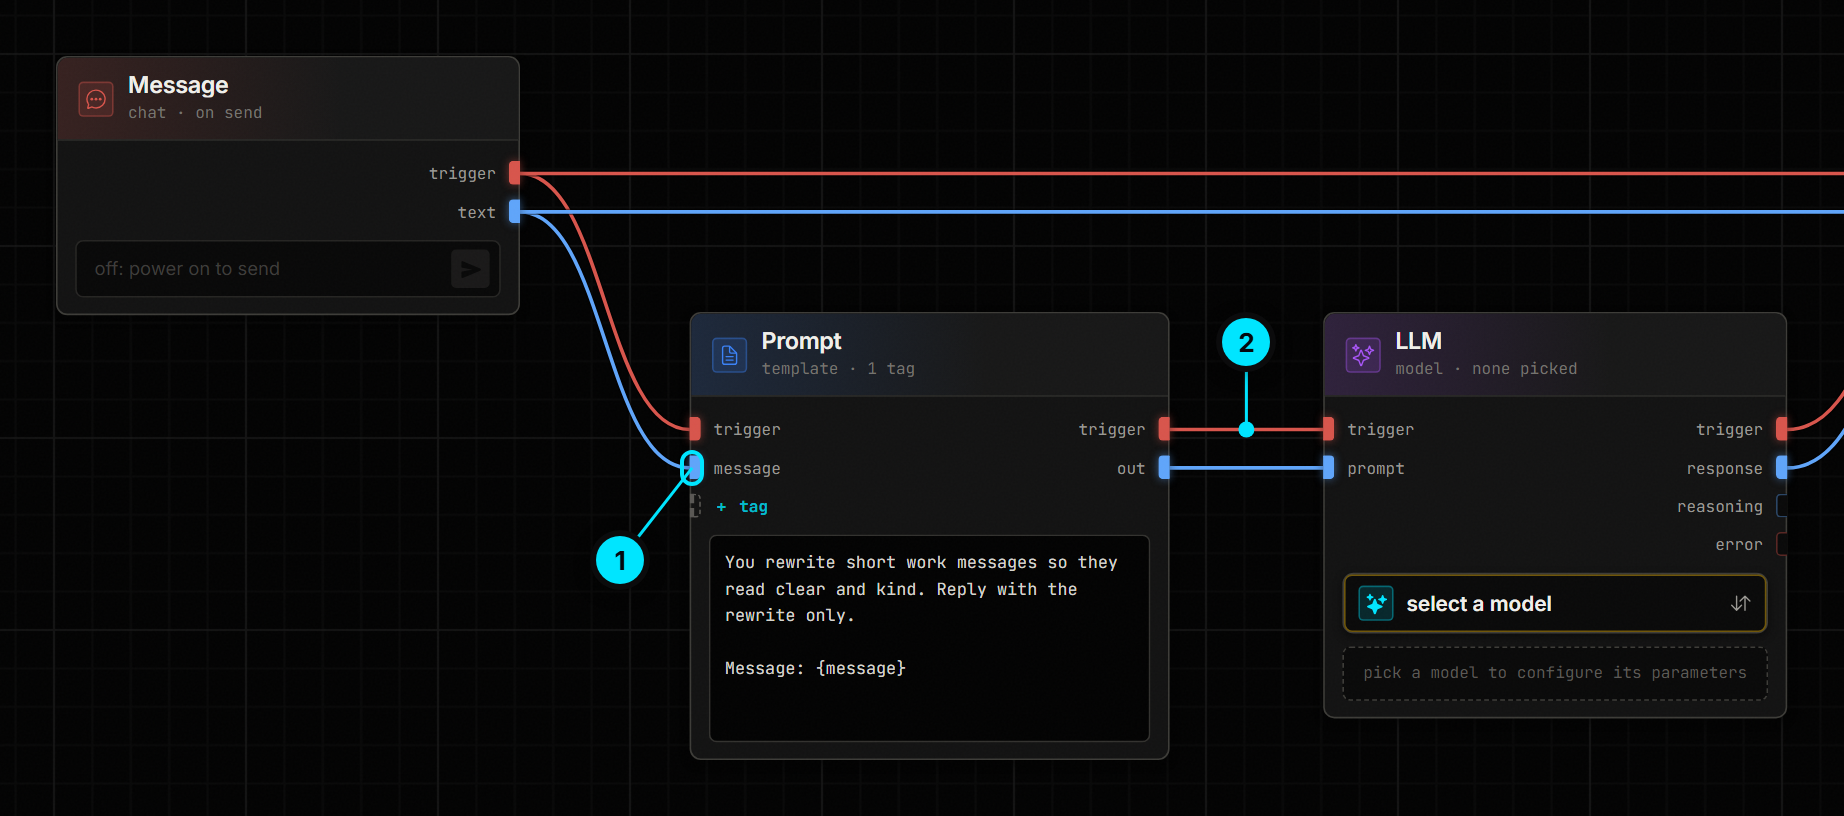
- The
messagesocket the wire from Messagetextmade. - The trigger runs through the Prompt to the LLM, so one message runs the model once.
The Chat sits right of the LLM. It takes the Message’s two wires on user_trigger and user, and the LLM’s two:
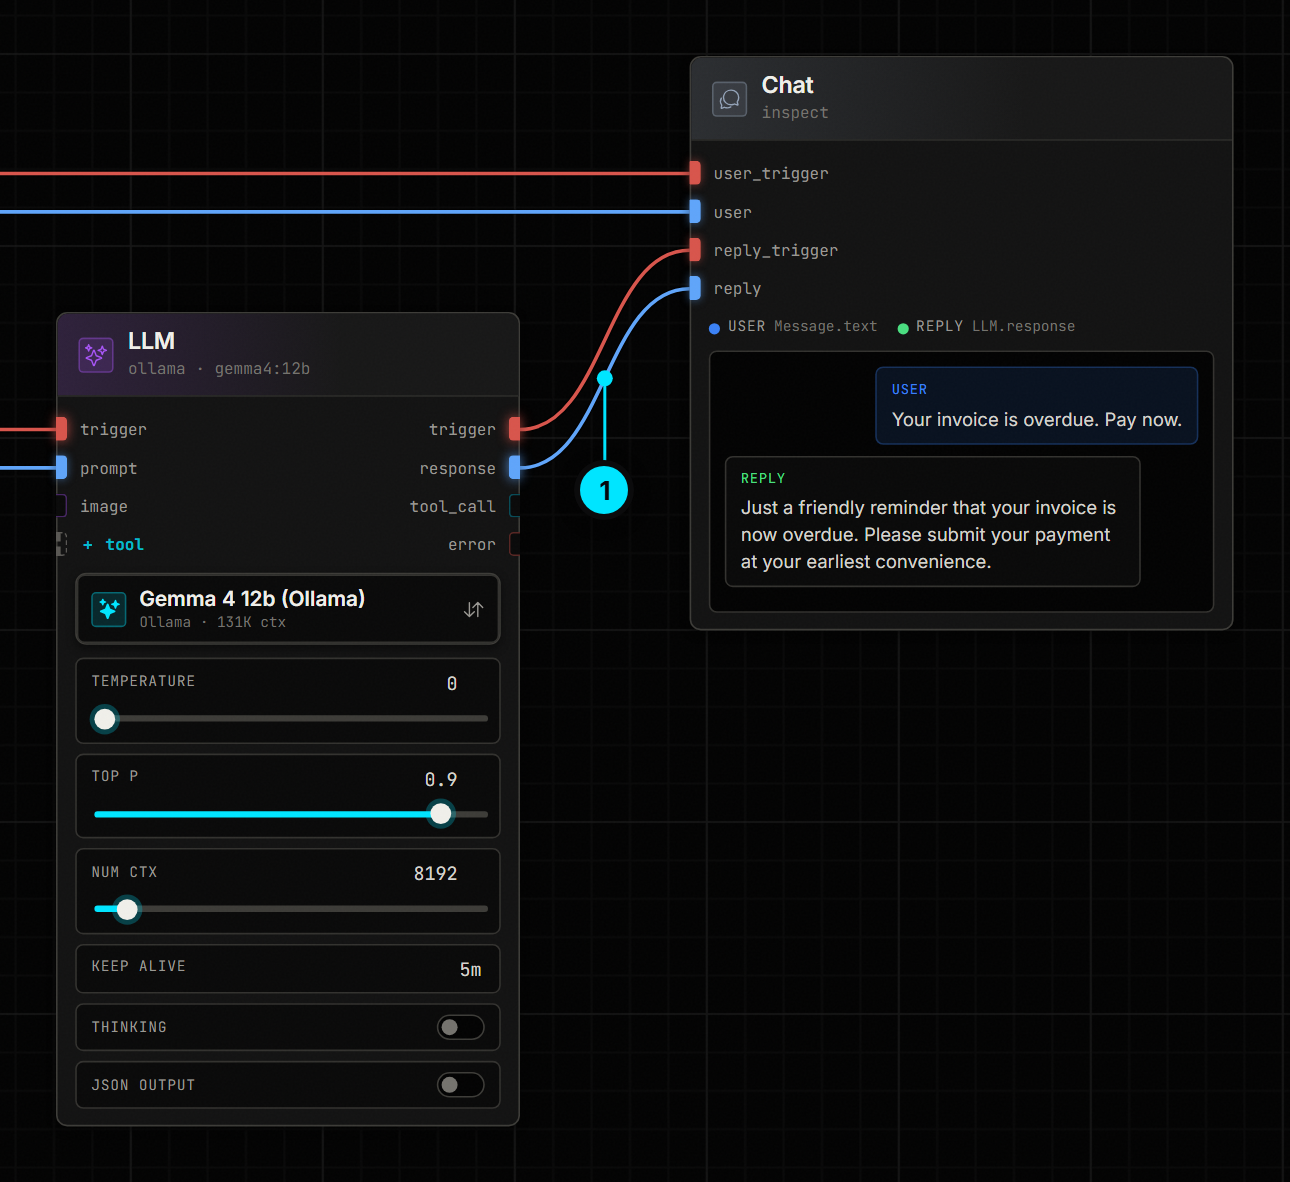
- The reply: LLM
responseinto Chatreply, with itstriggerintoreply_triggernext to it. The Chat shows the message and the rewrite, here with Gemma 4 12b picked.
4. Turn it On
Section titled “4. Turn it On”Press On and paste a message into the Message node, for example Your invoice is overdue. Pay now. The Prompt fires on the message and fills in your text, the LLM fires next and reads that prompt, and the rewrite lands in the Chat node.
If Ollama is not running, the LLM turns red, and its error output fires with the reason. If Ollama runs but the model is not pulled, the graph stays Off, and its problems list says to pull the model in Settings › AI Providers.
Keep the conversation
Section titled “Keep the conversation”This graph sends one message at a time: the model does not see earlier turns. The chat example that opens on the first start keeps the history in a SQLite table: a Database node, DB nodes that insert each message and read the last ones, and a Format List that turns the rows into lines for the prompt. Open it next to this one to see the pattern.
Change it
Section titled “Change it”- A cloud model. Add an Anthropic, OpenAI or xAI key in Settings › AI Providers and pick one of that provider’s models on the LLM node. Without the key, the node answers with a mock reply.
- The date in the prompt. Add a Time node named Date, wire its
outonto the Prompt’s+ tag(the tag is{date}), and writeToday is {date}.in the Prompt. - Reading images. A model that reads images (Gemma 4, Qwen3.5, Claude, GPT, Grok) grows an
imageinput on the LLM. Wire an Image or a Screen Capture into it.