Voice
A hands-free helper for the kitchen: your hands are covered in flour, so the answer has to be spoken, and short. The graph answers your messages out loud: the model writes a reply of one or two sentences, Strip takes out what should not be read aloud, and TTS turns it into a clip that plays in a Preview.
Download the graph and save it in user/graphs/, or build it below. The graph is MIT-0: copy it and license what you build from it however you like.
A voice costs money, so the downloaded graph picks no model and ships its TTS and Speaker disabled: it turns On as a text chat, and step 4 gives it its voice.
1. Add the key
Section titled “1. Add the key”In Settings › AI Providers, paste your xAI key. A TTS node without its key fails with an error that names the missing key.
2. The nodes
Section titled “2. The nodes”| Node | Settings |
|---|---|
| Chat Input, named Message | placeholder Ask while you cook... |
| Template, named Prompt | the text below |
| LLM | model: pick Gemma 4 12b (Ollama), or another model you pulled |
| Strip, named Speakable | every toggle on |
| TTS | model: pick xAI TTS (Grok voices), voice eve |
| Preview, named Speaker | autoplay on |
| Chat | none |
You are a hands-free kitchen helper. Answer in one or two short sentences, no lists.
User: {message}
A list or a long answer is hard to follow by ear, so the prompt asks for neither, and Speakable removes any markdown or emoji the model adds anyway.
3. The wires
Section titled “3. The wires”| From | To |
|---|---|
Message trigger |
Prompt trigger |
Message text |
Prompt message |
Prompt trigger |
LLM trigger |
Prompt out |
LLM prompt |
LLM response |
Speakable in |
LLM trigger |
TTS trigger |
Speakable out |
TTS text |
TTS trigger |
Speaker trigger |
TTS audio |
Speaker in |
Plus the four Chat wires, so the text shows too: Message into user and user_trigger, the LLM into reply and reply_trigger.
The {message} tag is named after the node its wire comes from. One message fires the Prompt, then the LLM, then the TTS, each once, so every reply is spoken once.
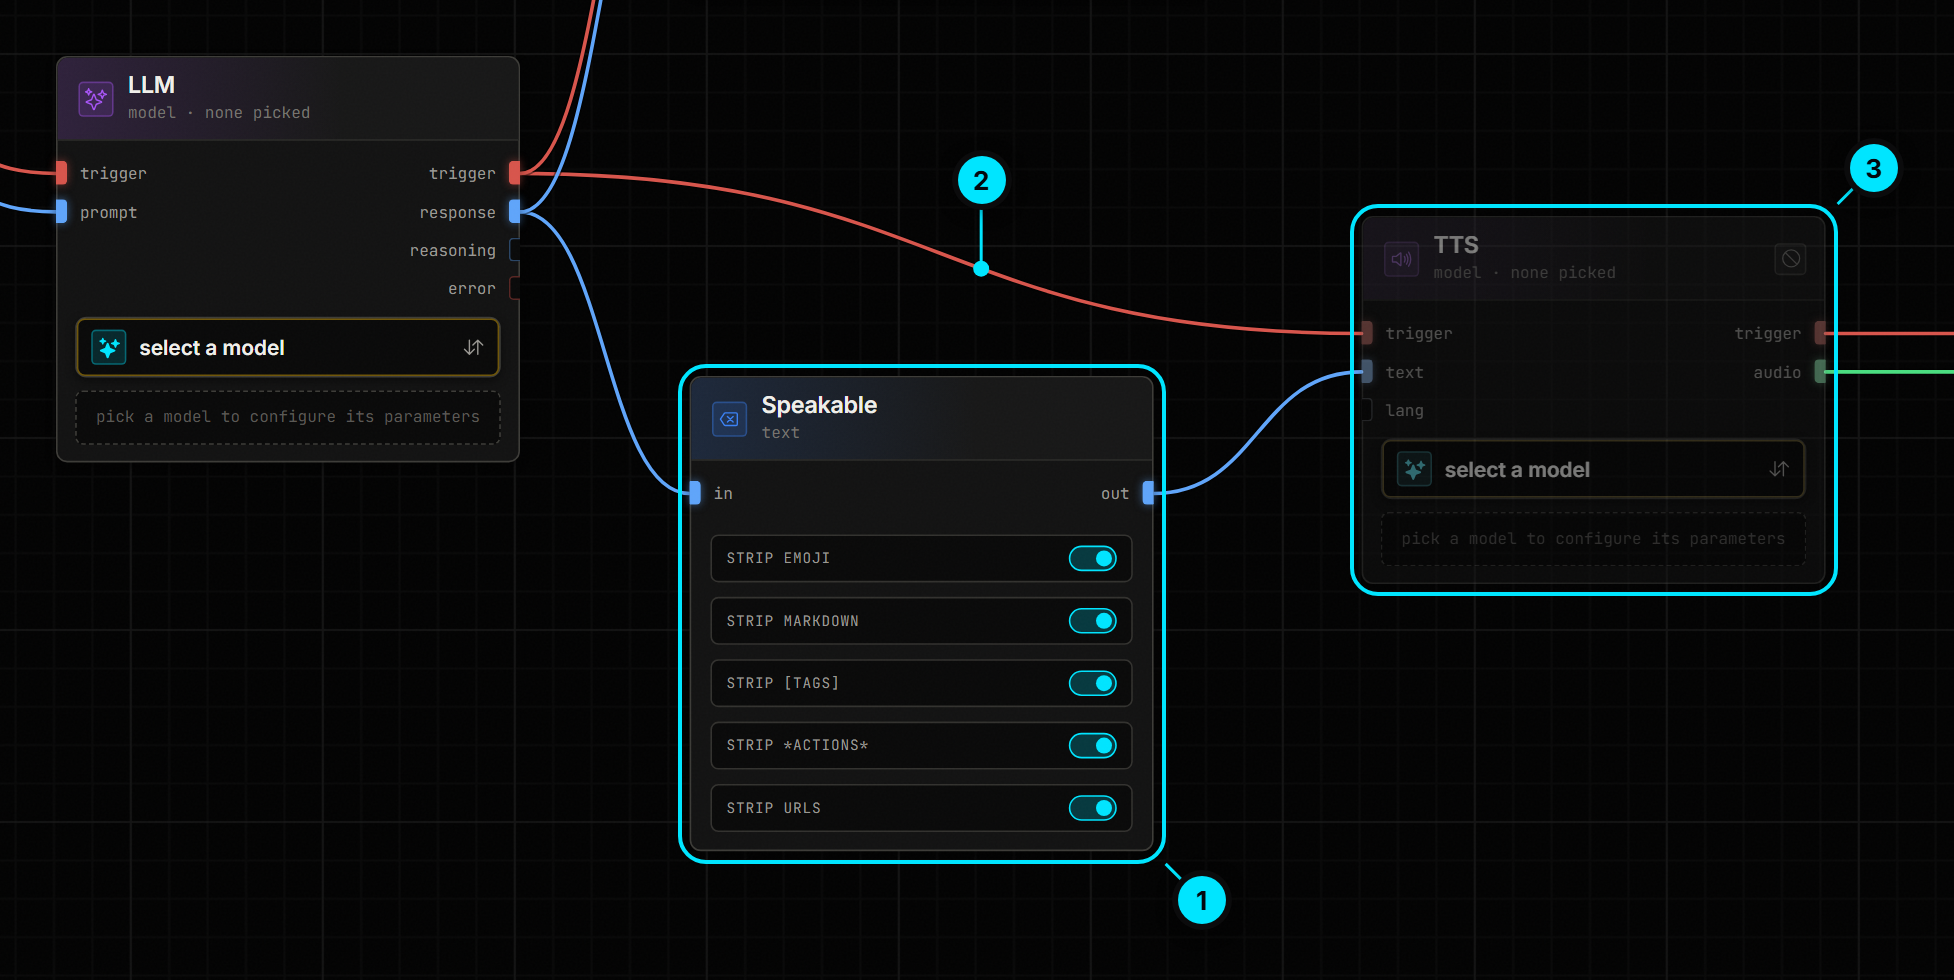
- Speakable cleans the reply for speech.
- The LLM’s trigger fires the TTS once per reply.
- The TTS, switched off as the graph ships (step 4 switches it on).
Right of the TTS, the Speaker takes its clip:
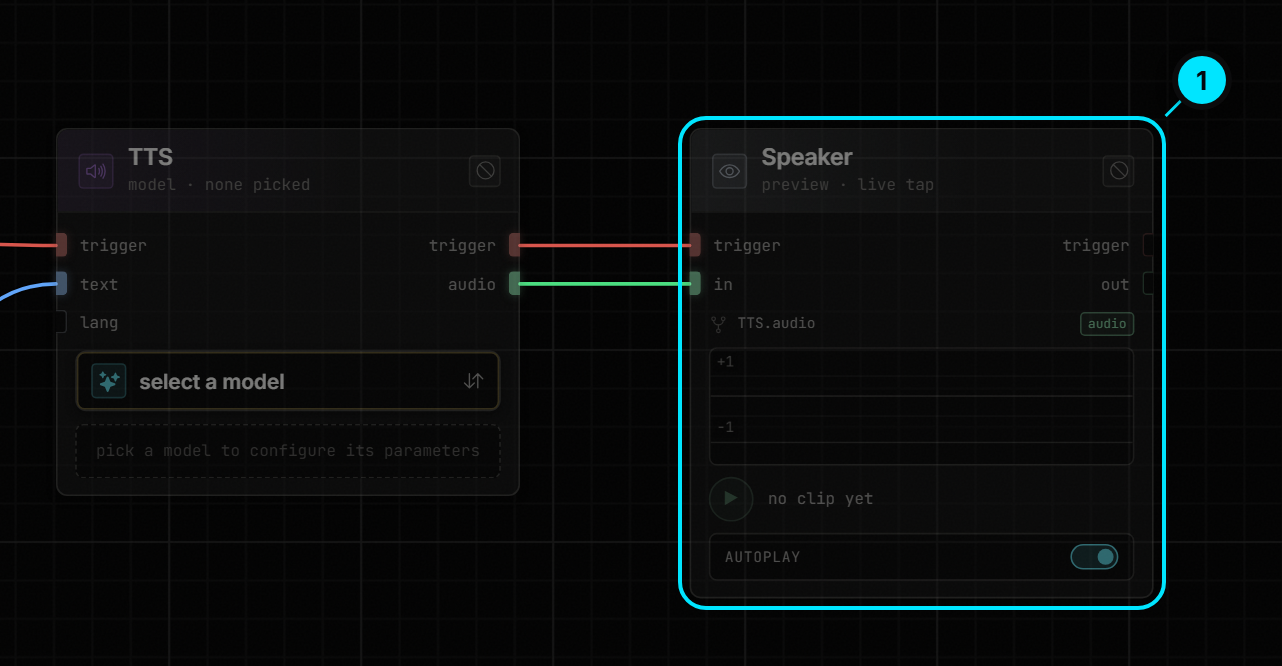
- The Speaker plays the clip, switched off as well.
4. Give it its voice
Section titled “4. Give it its voice”- Pick a model on the LLM node.
- Pick xAI TTS (Grok voices) on the TTS node, then right-click it and pick Enable.
- Right-click the Speaker and pick Enable.
Enable the TTS before the Speaker: a Speaker whose TTS is disabled gets nothing to play, and the graph stays Off until the TTS is back.
5. Talk to it
Section titled “5. Talk to it”Press On and ask something you would ask with your hands full, such as How long do I boil an egg for a runny yolk? The reply shows in the Chat node, and a moment later the Speaker plays it. After you pick Gemma 4 12b, the answer to that one was: “Boil the egg for about 6 to 7 minutes to achieve a soft-boiled egg with a runny yolk.” Try other voices from the TTS node’s voice knob; with the language on auto, xAI picks up the language of the text.
Speech in
Section titled “Speech in”STT turns a clip into text: pick a speech-to-text model on it, wire a data: audio value into its audio, fire its trigger, and its text goes where the Message node’s text went. Its lang output can go into the TTS lang input, so an xAI voice answers in the language you spoke.
The editor has no microphone button yet, so a clip comes from one of two places:
- A file. An Audio node reads a clip you put in
user/data/files, for examplequestion.wav. A Manual trigger can fire the STT. - Another program. An Audio Input node takes clips posted to it while the graph is On, as JSON with the install token:
curl -X POST http://127.0.0.1:8770/audio/<graph>/<Audio Input node> \ -H "Authorization: Bearer $(cat user/data/token)" \ -H "Content-Type: application/json" \ -d '{"audio": "data:audio/wav;base64,UklGR...", "lang": ""}'